Kimi vs Qwen: Three Official-App Tasks Tested
Kimi gave the more faithful report summary in our three-task comparison. Both apps got the event-budget calculation right. Neither produced a slide deck we could recommend presenting unchanged. Kimi’s slide table preserved the supplied numbers, but its chart distorted them; Qwen’s deck changed several figures and the budget year.
We compared the international websites, Kimi and Qwen Studio, using the same inputs for a research brief, a revised event quote and a six-slide presentation. One important difference: Kimi automatically used an existing account skill on the quote and slides. Those results reflect that account’s app experience, not a clean comparison of the underlying models.
By China AI Chat Team. App trials conducted 24 September 2026; product sources rechecked 28 September 2026. This independent guide is not affiliated with Moonshot AI or Alibaba.
Three tasks, three different decisions
| Your task | What Kimi did | What Qwen did | What matters before you use it |
|---|---|---|---|
| Summarize an IEA report | Closer to the source, with useful report-page links; Europe’s sales figure was less precise than the chapter | Overstated Europe’s sales and linked the general report page; other figures lost precision | Open the cited chapter and compare each figure with the source |
| Check a revised event quote | Correct conditional totals, with an account skill automatically involved | Correct conditional totals and missing-date warning | Confirm the deposit date; the input was pasted text, not an uploaded PDF |
| Create a board presentation | Correct written figures but misleading chart heights; account skill involved | Changed source counts, rates and the budget year | Neither first deck was ready to present; usable downloads and editable PPTX export were not verified |
These were first outputs from three tasks on signed-in accounts. They do not establish an overall winner, an error rate or a free-tier comparison. The chat interfaces displayed K3 High in Kimi and Qwen3.7-Plus in Qwen Studio; slide creation used each app’s dedicated route. The visible labels do not identify every backend model involved.
Research: will the answer preserve the source’s figures?
The task was a short transport briefing based only on the IEA’s Global EV Outlook 2026; we checked the figures against its trends chapter. We requested 2025 sales and market shares for the world, Europe and China, exact report-page links, and fewer than 180 words. The prompt also asked the apps to retain approximations such as “more than” and “almost.”
Kimi stayed closer to the report. It reproduced the global and China figures and Europe’s 28% share. For Europe’s sales, it gave “more than 4 million” rather than the chapter’s 4.2 million. That broader number is consistent with the report, but loses useful detail. Its answer included direct links to the executive summary and trends chapter.
Qwen introduced a material error: Europe’s sales became “more than 5 million.” It also replaced several requested figures with looser approximations. The distinction matters: its China lower bounds were not logically false, but they did not convey the figures the source supplied. Its citations all pointed to the report’s general landing page.
| IEA 2025 check | Kimi's first answer | Qwen's first answer |
|---|---|---|
| Global sales: more than 20m; share: 25% / one-quarter | Both figures with the source's approximate wording | More than 20m; “almost 25%” softened the stated share |
| Europe: 4.2m; 28% | “More than 4m”; 28%. Correct but less specific volume than the chapter provides | “More than 5m”; “almost 30%.” Sales volume is wrong; share is less precise than the requested 28% |
| China: more than 13m; almost 55% | Both source figures | “More than 12m”; “more than 40%.” Broad lower bounds that miss the requested figures |
| Exact report-page links | Linked the executive summary and trends chapter | Linked only the report home four times |
For a briefing like this one, Kimi’s answer would require less correction. You would still need to recover the more precise Europe figure. With either app, compare the number, year, region and meaning of a percentage with the original chapter. A relevant citation alone does not show that the surrounding sentence is accurate.
Event quotes: can the answer follow changed terms?
Our fictional two-page quote contained an older proposal and a later change order. Page 1 used 120 attendees, catering at $18 each and a $440 audio-visual rental. Page 2 replaced those terms with 110 attendees, catering at $20 each and AV included at $0. Venue hire stayed at $1,850, with a 10% discount only if a deposit arrived by 20 September 2026. The source deliberately omitted the deposit receipt date.
Both apps received the same page-labelled text in fresh chats. This tested reasoning over pasted text, not PDF upload or extraction. The committee’s budget was $4,000, so the answer needed two possible totals and a clear statement of what had to be confirmed.
Both calculated the two outcomes correctly
| Deposit received | Calculation from the revised terms | Total | Against the $4,000 cap |
|---|---|---|---|
| By 20 September 2026 | $1,665 venue + $2,200 catering + $83.25 tax | $3,948.25 | $51.75 under |
| Later | $1,850 venue + $2,200 catering + $92.50 tax | $4,142.50 | $142.50 over |
The fictional quote applies 5% tax to the payable venue charge; catering is not taxable and AV costs $0. Both first answers followed page 2, showed the correct arithmetic and budget differences, and kept approval conditional on confirming the deposit date. Both separated optional $180 parking and the $450 fee for cancellation after 15 October from the upfront total.
Kimi’s result had an additional influence. After submission, it automatically invoked a pre-existing account-level custom skill. We did not install or select the skill for this trial. It affected the response format and may have helped source handling, so the result cannot be credited solely to an unaided Kimi model. Qwen also reached the correct conditional recommendation and cited the relevant pages.
The decision still depends on the missing date—and parking
Even the discounted total leaves only $51.75 to spare. Adding optional parking would bring it to $4,128.25, or $128.25 over budget. That is a separate calculation from the same source terms, not another app test. Before approving a real quote, establish which version controls, confirm the discount condition and decide which optional costs you actually need. Correct arithmetic cannot supply a missing receipt date.
Slides: do the visuals tell the same story as the data?
We gave Kimi Slides and Qwen Studio’s Slides mode the same six-slide brief for a fictional nonprofit. It supplied 2024 and 2025 enrollments, completions and reported job placements, followed by a 2026 funding decision. The deck needed accurate figures, clear rate denominators, a comparison visual, a conditional board decision and two verification checks.
Both produced six visually readable slides. Neither first deck was ready to present. Kimi preserved the written data but drew a misleading comparison chart. Qwen changed numbers and the budget year. Kimi again invoked the existing account skill automatically, which limits any comparison of the underlying models.
| Source packet and check | Kimi Slides' first deck | Qwen Slides' first deck |
|---|---|---|
| 2024: 400 enrolled, 260 completed, 143 reported placements | All three retained in its written comparison table | A later comparison slide showed 150 enrolled and 85 placements; other values also shifted |
| 2025: 480 enrolled, 336 completed, 202 reported placements | All three retained in its written comparison table | A later comparison slide showed 180 enrolled and 120 placements |
| Completion 65.0% → 70.0%; placement among completers 55.0% → 60.1% | Correct written rates and definitions | Different slides displayed inconsistent, unsupplied rates, including 72%/78% completion on one and 65%/68% on another |
| 2026 budget $120,000, committed $90,000, gap $30,000 | Year and arithmetic correct; funding bar shows the 75%/25% split | Arithmetic correct, but the deck's funding slide called it a 2025 budget |
| Board safeguards | Conditional vote with placement-record and funding-source checks | Two verification gates, but the year and data errors would mislead a board if left uncorrected |
Kimi: correct labels, incorrect bar heights
Kimi’s written table kept all six source counts and the correct rates. Its chart did not plot those values correctly: the bar labelled 400 stopped below the 200 gridline on a 0–500 axis, while the bar labelled 65.0 reached only around the 30 gridline on a 0–100 axis. Reading the labels without looking at the axes would miss the problem.
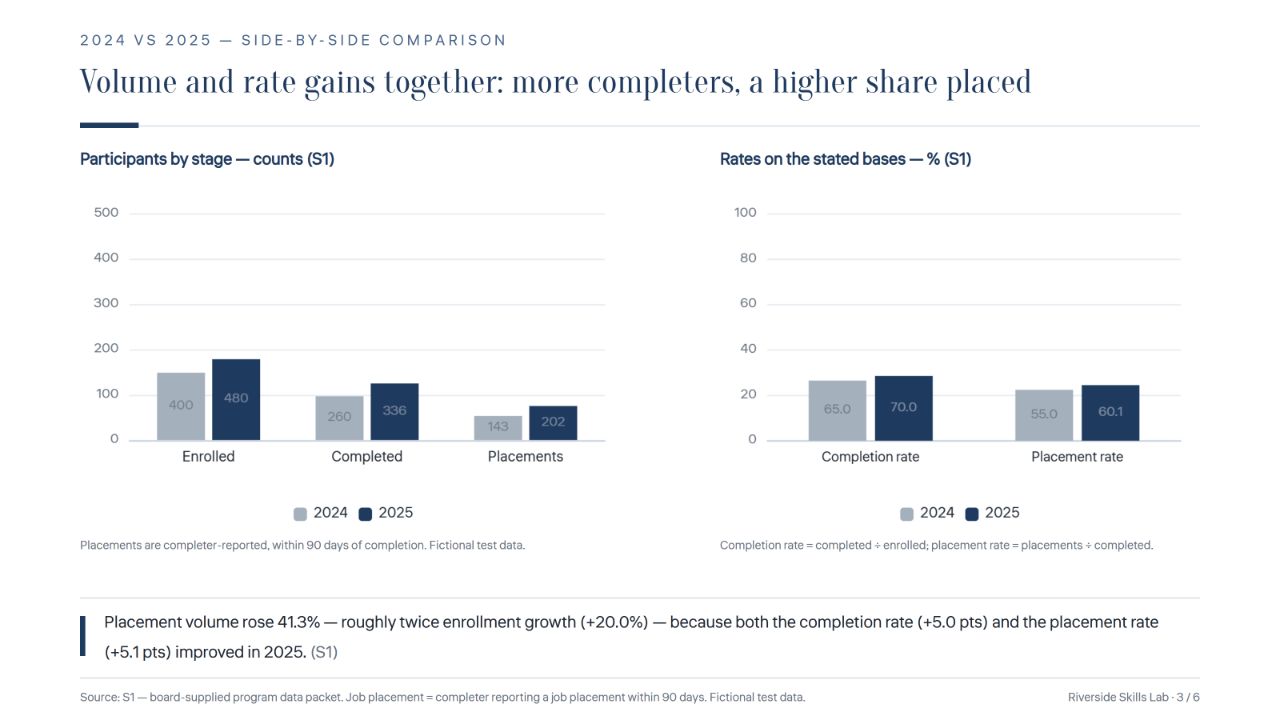
The separate funding bar did show the $90,000 committed and $30,000 gap in the correct 75%/25% proportion. The deck retained the 2026 budget year and proposed a conditional decision with checks on placement records and funding sources. Those correct elements do not make the faulty comparison chart suitable for a board presentation.
Qwen: the deck changed the supplied facts
Qwen’s slide 3 used 150 and 180 enrollments instead of 400 and 480, and 85 and 120 placements instead of 143 and 202. Its 72%/78% completion rates were not in the input; another slide used 65%/68%, so the slides also disagreed with each other. The cover said 2026, but the description and funding slide called it a 2025 budget.
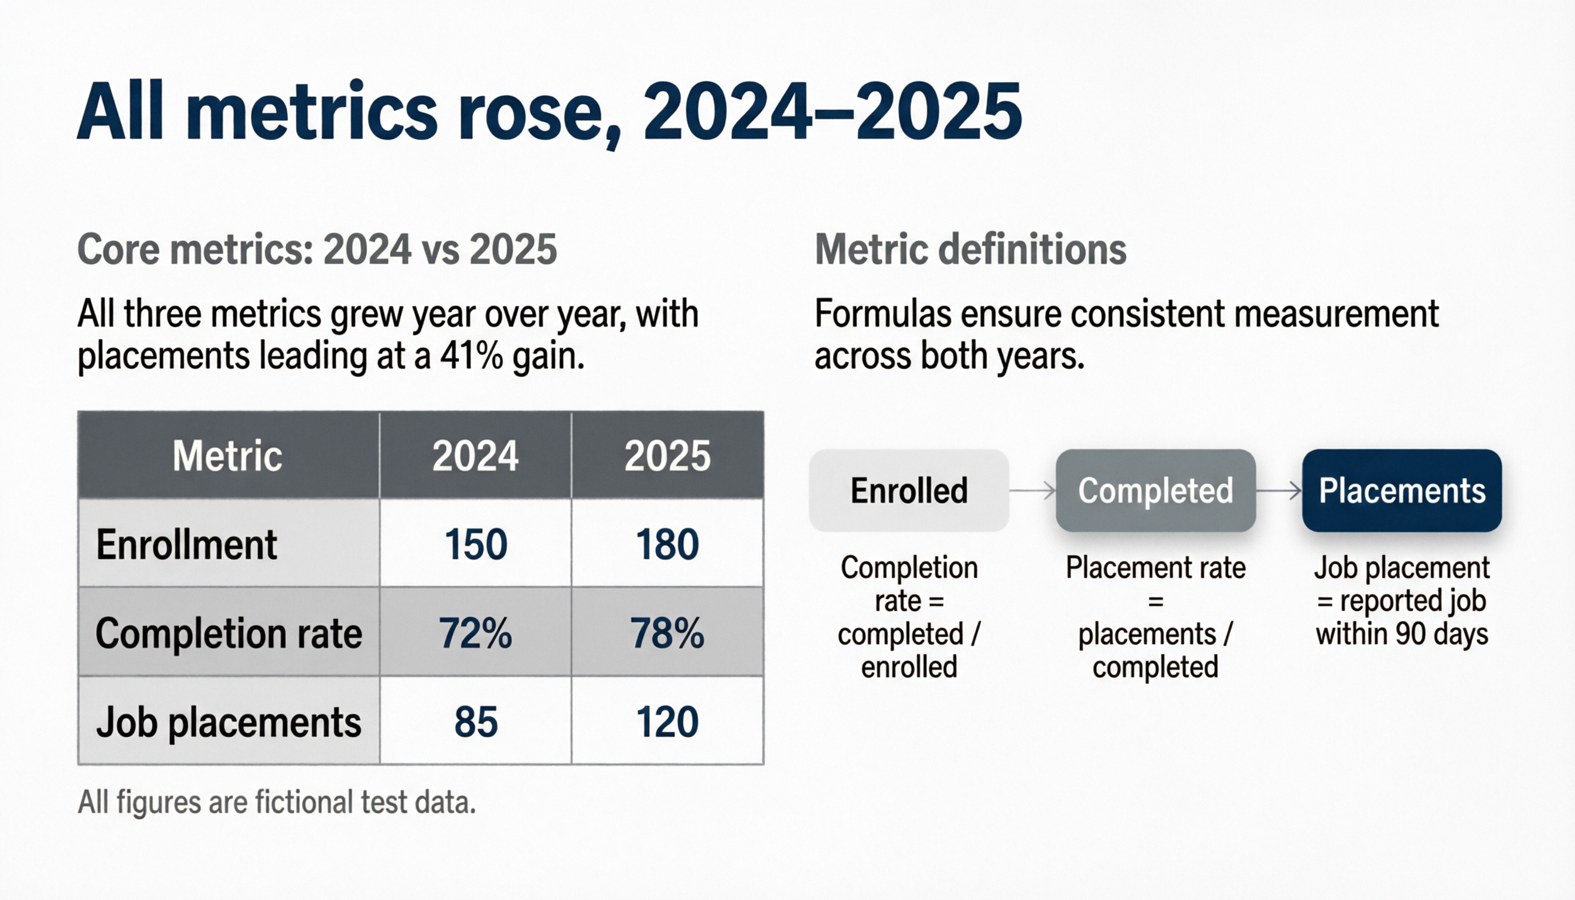
One sentence attributed growth to sustained demand for training, a cause the fictional packet did not establish. Qwen calculated the $30,000 funding gap correctly and included two verification gates, but those strengths do not resolve the changed figures, year or unsupported explanation.
What to check before presenting or exporting
Compare each slide with the source: values, years, what each percentage divides by, and where bars sit against the scale. A correct table does not guarantee a correct chart. If a deck explains why a result changed, check that the source actually supports that explanation.
Usable file export was not verified for either deck. We invoked both download actions but could not independently open the resulting files. Editable PowerPoint (PPTX) export therefore remains unverified too. These findings concern the visible slide previews. For the Kimi interface and export route, see our Kimi Slides guide.
Which should you try for your task?
- For a brief based on a public report: Kimi is the better starting point suggested by this one result. It followed the IEA source more closely and provided more useful links. Check the next report independently; one answer does not establish general research reliability.
- For changed terms and conditional arithmetic: either app produced a useful answer to this fictional packet. Try a small example where you already know the correct totals, and include any relevant account skills or settings when judging the result.
- For a board deck: Kimi supplied the more faithful written draft here, with account-skill assistance, but its comparison chart needs correction. Qwen’s changed figures require checking against the original source. Budget time to review the entire deck and confirm the file opens in the software you plan to use.
Start with a small, non-sensitive task that resembles your own work and that you can verify. The useful question is how much checking and correction the output requires before you can use it.
Access, plans and the other Kimi and Qwen products
Kimi’s feature directory lists dedicated Docs, Sheets, Slides and Deep Research routes. Its membership guide explains plan access and credits. Qwen’s official product page distinguishes its consumer product from the API platform. We did not run matched Docs, Sheets or Deep Research quality tests here.
Check the route and allowance shown in your own account before paying for a task. Kimi displayed Moderato during these trials, and the accounts were not matched for subscription tier or credit budget. This comparison does not establish which free tier or paid plan offers better value. Our Kimi pricing and Qwen pricing guides cover those separate questions.
Region also matters. Alibaba’s Qwen App commerce and booking announcement described a public test in China. We did not test those services or verify them as global Qwen Studio features.
For development work, compare an exact model and delivery route. The Kimi models and Qwen models guides cover model choices; the Kimi API and Qwen API guides cover integrations. The Kimi Code and Qwen Code guides address coding workflows. These consumer-app results do not measure API speed, cost, coding-agent quality or local deployment.
Test conditions and original files
The trials took place on 24 September 2026 in signed-in international versions of the official websites. Kimi displayed Moderato membership and K3 High. Qwen Studio displayed Qwen3.7-Plus, with Web search and Auto visible for the research request. These are observed interface conditions, not verified backend model IDs or equivalent paid plans.
Each app received one initial request per task. Qwen’s Slides workflow also required an unchanged outline confirmation. We retained the first outputs without regenerating, repairing or refining them. Kimi’s existing account skill was automatically involved in the quote and slide tasks; those results cannot isolate model quality.
| Shared task | Same input and checks | What it can tell you | What it cannot tell you |
|---|---|---|---|
| Current-source briefing | The same prompt asking for 2025 electric-car sales and shares from the IEA's Global EV Outlook 2026, with exact report links | Whether these particular first answers retrieved and expressed the requested facts and citations | General research accuracy, reliability, speed or search quality across topics |
| Revised event quote | The same page-labelled text extracted from a new fictional two-page quote and the same conditional-budget question | Whether the first answers reconciled a newer change order and transparent arithmetic | PDF-upload handling; the browser file chooser did not open, so the source was pasted as text. Kimi's automatic account skill also prevents an unaided model comparison. |
| Board slide briefing | The same six-slide brief and fictional 2024–2026 data packet in each app's dedicated Slides workflow | Whether these particular generated decks retained counts, rates, year, checks and readable visuals | Overall slide quality, editable PPTX export, template choice, equal entitlements or an unaided model comparison. Kimi automatically used an account skill here too. |
The first two tasks’ protocol was fixed before submission. The switch to pasted quote text and the separate slide brief and checks were also recorded before either app received those respective inputs. Our research method explains the distinction between provider claims, observations and independently checked results.
Access interruptions, input changes and download details
Qwen’s research request paused at an account-verification slider. The account owner completed it and the same request resumed; there was no rerun, model switch or regenerated answer. This was an access interruption, not an incorrect response.
The file chooser did not open for the quote task, so both apps received identical page-labelled text instead of the PDF. The original fictional PDF is included in the evidence package for inspection; it was not uploaded in these trials.
For slides, Qwen drafted an outline and we replied only Confirm, without changing it. Kimi’s export menu showed Slides, Image and PDF, while Qwen’s output card had a PDF marker and its preview offered Download. Both download actions were invoked, but neither resulting file was independently opened. This does not establish whether either service offers editable PPTX in other circumstances.
This small comparison does not measure reliability rates, speed, every plan or every task. Two tasks used fictional data. The slides were assessed in their visible previews, and the quote results concern pasted text. The outputs and material failures remain in the record.
Download the complete test record (ZIP, 1.2 MB): frozen prompts and checks, the page-labelled fictional quote, four first chat answers, the slide brief, six Qwen slide previews and the Kimi chart capture. Private account links, identifiers, custom-skill instructions and credentials are excluded.
We will revisit the comparison when changes to access, visible models, research or document workflows, or plan rules affect the reader’s decision. To report a reproducible error, contact the editorial team with the source and section to correct.