Independent comparison / Consumer web chats
Qwen vs ChatGPT: comparing the web assistants
Our Qwen vs ChatGPT test found no answer-quality winner across four small English text tasks: every completed answer met our checks. The session experience did differ. ChatGPT Free completed all eight requests; Qwen returned seven complete answers across eight requests, with one unanswered request and one extra blank alternative. These observations do not establish which assistant is better overall.
We compared the observed Qwen Chat session, labelled Qwen3.7-Plus in Fast mode, with ChatGPT Free, whose serving-model version was not exposed. Each task received two fresh-chat attempts in each app on September 22, 2026. This is a consumer-chat comparison, not a benchmark of API models, paid tiers or coding agents.
By China AI Chat Team. Tested and reviewed September 22, 2026 (UTC). Research, collection and editorial checks were AI-assisted. See our methodology. ChinaAI is independent of both providers.
Results: correct completed answers, with two blank slots
We submitted 16 requests across four tasks. A full pass requires a completed answer that meets every predefined factual and formatting condition. If an app supplies alternatives, all must complete and pass. A blank slot is recorded as unavailable, not as a wrong answer.
| Task | Qwen: two requests | ChatGPT Free: two requests |
|---|---|---|
| Customer email | 2 full passes | 2 full passes |
| Conflicting records as JSON | 1 full pass; 1 request with no answer | 2 full passes |
| Parcel quote with conditional discount | 2 full passes | 2 full passes |
| Python label-cleaning function | 1 full pass; 1 correct function plus a blank alternative* | 2 full passes |
*Qwen’s second coding request displayed two alternatives. One contained a complete function that passed all 10 checks; the other remained blank. We kept both slots and selected neither. Overall, the collection contains 15 completed answers and two blank slots, because that request offered two alternatives.
ChatGPT completed every request in this session. That does not establish better reasoning or uptime: there were only two attempts per prompt.
Which Qwen and ChatGPT did we test?
Qwen’s official product page presents Qwen Chat as an assistant powered by the Qwen model series. OpenAI’s ChatGPT guide distinguishes conversational Chat from Work and Codex workflows, and notes that features vary with access and configuration. We used the plain web chats below.
| Observed setting | Qwen Chat | ChatGPT |
|---|---|---|
| Official web app | chat.qwen.ai | chatgpt.com |
| Account plan | Not displayed in the chat view | Free |
| Model label | Qwen3.7-Plus | Serving-model version not exposed |
| Mode and tools | Fast; Tools switch off | Think unpressed; no search tool selected |
| Conversation | Fresh chat per request | Fresh temporary Unpersonalized chat per request |
| Inputs | English text only | English text only |
Every prompt also asked the app not to search. ChatGPT’s temporary-chat notice said memory, plugins and custom instructions would be ignored. That is a description of the displayed setting, not an independent privacy audit. Visible settings do not make hidden computation, instructions or backend routing equivalent.
What happened to availability?
- Qwen: a generic HTTP 502 notice appeared around the first email, whose complete answer we retained. The first JSON request also showed a 502 notice and produced no answer before we clicked Stop after about 96 seconds. The second coding request had a blank alternative after at least 106 seconds; we stopped it without choosing a preference. Its other alternative was complete. We cannot establish the causes from the interface.
- ChatGPT Free: after the second calculation, a notice said files, images and data analysis were temporarily unavailable, while text chat could continue. Our remaining tasks used text only and completed. No serving-model change was displayed; the backend remained unverified.
The decisions to stop stalled outputs were made during collection, not as part of a predefined speed test. We did not replace those slots with retries, buy an upgrade or call a paid API. These observations are not comparisons of daily quotas or subscription value. For Qwen’s separate access and API costs, see Qwen pricing.
Writing: both preserved the customer’s choices and deadlines
The email task combined eight factual obligations with a 95-word body limit: the order reference, original delivery date, estimated replacement window, no guaranteed day, keep/cancel choices, reply deadline and refund-processing condition. It tested faithful rewriting rather than creative style.
Read or copy the exact prompt
Write a concise, polite customer email using only this fictional support case. Do not search the web. Include every fact and option listed below, without adding promises, discounts, faster shipping or a tracking link.

Customer: Morgan.
Order: RB-2416.
Original expected delivery date: 8 December 2026.
Updated estimated delivery window: 10–12 December 2026. No particular day is guaranteed.
The customer may keep the order or cancel it for a full refund.
To cancel, the customer must reply by 18:00 UTC on 7 December 2026.
Refund processing takes 3–5 business days after cancellation is confirmed.

Return only the email in plain text. Put one nonempty subject line first, beginning "Subject:". Greet Morgan. Keep the body to at most 95 whitespace-separated words, counting the greeting and closing but excluding the subject line. End with these two lines:
Regards,
Brightdesk Support
Both apps passed in both runs. They retained the cancellation option and tied the 3–5 business-day refund period to confirmed cancellation, rather than merely to the customer’s reply. Neither added a material promise. The body counts were 69 and 68 words for Qwen, and 61 and 71 for ChatGPT, including greeting and closing.
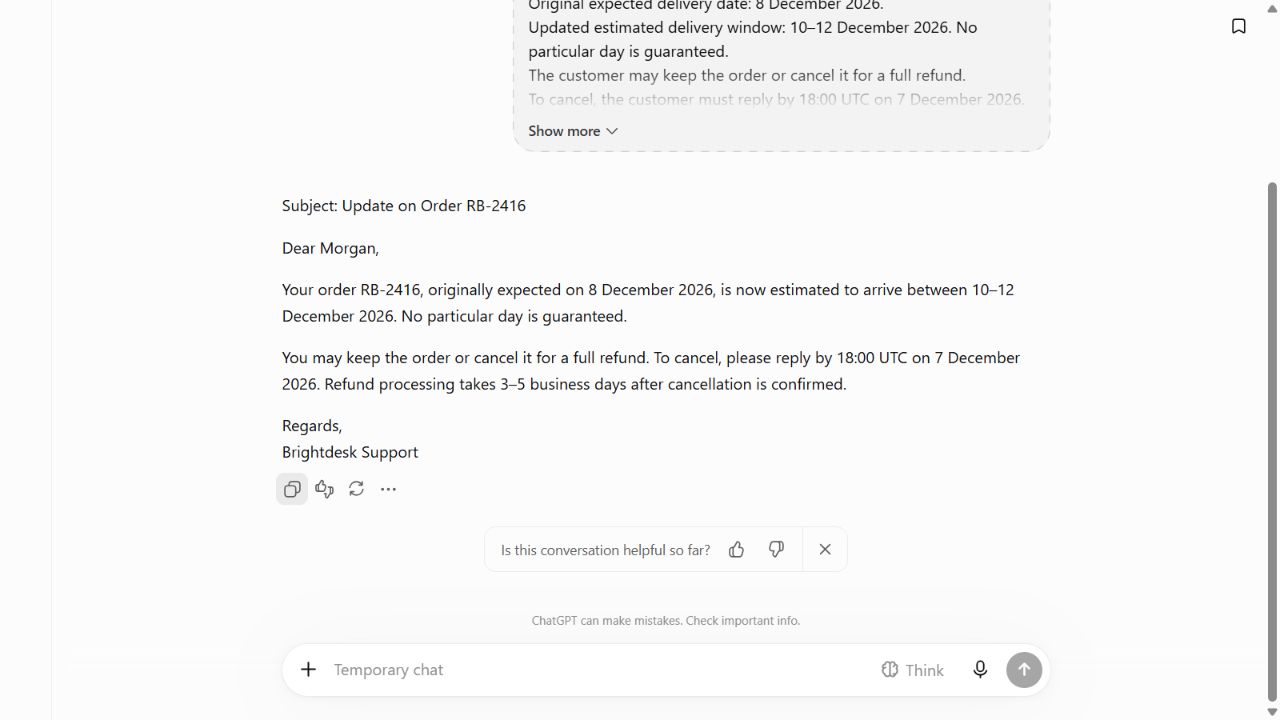
Here is ChatGPT’s first answer, unchanged:
Subject: Update on Order RB-2416

Dear Morgan,

Your order RB-2416, originally expected on 8 December 2026, is now estimated to arrive between 10–12 December 2026. No particular day is guaranteed.

You may keep the order or cancel it for a full refund. To cancel, please reply by 18:00 UTC on 7 December 2026. Refund processing takes 3–5 business days after cancellation is confirmed.

Regards,
Brightdesk Support
Check this in your own writing: verify what triggers a refund, who must act and which date is only an estimate. A shorter or more polished email is not better if it changes those obligations. This test provides no reason to prefer one app’s writing accuracy on these two attempts.
Data extraction: a conflict is different from missing information
Three fictional records updated different parts of a reservation. Two equally recent records disagreed on the room; none supplied an email address. The app had to retain older fields that were not replaced and distinguish an unresolved conflict from an entirely missing value.
Read or copy the exact prompt
Use only the fictional reservation records below. Do not search the web. Resolve each field separately: use the latest dated record that states that field, carrying earlier fields forward if later records do not update them. The date field means the reservation date; record issue dates determine priority only. Records with the same date have equal priority; their listing order does not break a tie. If equally latest records disagree on a field, set that field to null and list its name in conflicts. For an entirely missing field, use null without adding it to conflicts.

Record A, issued 2 November 2026: Reservation MT-482 is for 18 November 2026 at 14:00, in room Orion, for 12 attendees. Its budget is USD 180.
Record B, issued 4 November 2026: For reservation MT-482, change the start time to 14:30, the room to Lyra, and the attendee count to 16.
Record C, issued 4 November 2026: For reservation MT-482, the room is Vega.
No record provides a contact email.

Return one JSON object with exactly these keys: reservation_id, date, start_time, room, attendees, budget_usd, contact_email, conflicts. Use strings for reservation_id/date/start_time, a string or null for room, an integer for attendees, a number for budget_usd, a string or null for contact_email, and an array of field-name strings for conflicts. Format date as YYYY-MM-DD and start_time as HH:MM. No Markdown or other text.
Both ChatGPT answers and Qwen’s second answer passed all eight fields, their types and strict JSON formatting. Qwen’s first request produced no completed answer, so its extraction accuracy could not be assessed. This is the expected object, formatted here for readability:
{
  "reservation_id": "MT-482",
  "date": "2026-11-18",
  "start_time": "14:30",
  "room": null,
  "attendees": 16,
  "budget_usd": 180,
  "contact_email": null,
  "conflicts": [
    "room"
  ]
}
The key distinction is "conflicts": ["room"]. Both room and email are null, but only the room is disputed. The budget and reservation date remain valid because the later records never replace them. We also checked for extra or duplicate keys, Markdown fences and numbers returned as strings.
Define source priority and missing-value rules, then validate the JSON before passing it to software. This small task cannot establish reliability across schemas or documents.
Calculation: both kept the surcharge outside the discount
The fictional parcel quote required rounding started kilograms upward, checking a discount threshold against the correct subtotal, and adding an undiscounted zone surcharge afterward.
Read or copy the exact prompt
Calculate this fictional parcel quote using only the rules below. Do not search the web.

The parcel weighs 5.3 kg and is going to the Outer zone.
The charge for the first 2 kg is USD 4.50. Above 2 kg, each started additional 1 kg costs USD 1.20: round the additional weight up to a whole number of kilograms. The base delivery price is the first-2-kg charge plus the additional-weight charge.
If the base delivery price before the zone surcharge is at least USD 8.00, apply a coupon discount of 20% to that base price. Otherwise, apply no coupon discount.
After any coupon discount, add the Outer-zone surcharge of USD 3.00. The surcharge is never discounted and does not count toward coupon eligibility. No taxes or other charges apply.

Show the additional weight, number of charged additional-kilogram blocks, additional-weight charge, base delivery price, coupon eligibility, discount amount, zone surcharge, and final amount due in USD. Round monetary results to two decimal places.| Required step | Independent expected result |
|---|---|
| Additional weight | 5.3 − 2 = 3.3 kg |
| Charged blocks | Round 3.3 upward: 4 |
| Additional-weight charge | 4 × USD 1.20 = USD 4.80 |
| Base delivery price | USD 4.50 + 4.80 = USD 9.30 |
| Coupon eligibility | Yes: USD 9.30 ≥ USD 8.00, excluding the surcharge |
| Discount | 20% × USD 9.30 = USD 1.86 |
| Outer-zone surcharge | USD 3.00, not discounted |
| Final amount | USD 9.30 − 1.86 + 3.00 = USD 10.44 |
All four answers showed the required steps and reached USD 10.44. ChatGPT used a compact table in its first response and bullets in its second; Qwen used a longer step-by-step layout. We did not score length or layout as correctness.
Check this in your own calculations: identify which subtotal controls eligibility and which charges are excluded before applying a percentage. Our example tests one eligible parcel, not below-threshold quotes, every weight boundary or spreadsheet analysis.
Coding: all four completed functions passed 10 checks
The Python task asked for a small helper that trims and lowercases labels, removes empty values and duplicates, preserves first-occurrence order and internal whitespace, and leaves the input list unchanged.
Read or copy the exact prompt
Implement a pure Python function named clean_labels(labels). You may assume labels is a list of strings containing only ASCII characters.

For each string, remove leading and trailing whitespace, convert letters to lowercase, and discard the result if it is empty. Remove duplicates after normalization, keeping the first occurrence of each normalized label in its original order. Preserve whitespace inside a label. Return a list of strings and do not mutate the input list. Do not search the web.

For example, clean_labels(["  Blue", "RED", "blue", " ", " Green "]) must return ["blue", "red", "green"].

Return only the function in one Python code block. Do not add imports, tests, explanations or top-level executable code.
We inspected and executed the returned functions without repairs under Python 3.12.14. All four completed functions passed the same 10 predefined checks. Qwen’s second function came from the complete alternative of a partly completed request; its blank companion is still recorded and prevents a full request-level pass.
This is Qwen’s unchanged first response:
```python
def clean_labels(labels):
    seen = set()
    result = []
    for label in labels:
        normalized = label.strip().lower()
        if normalized and normalized not in seen:
            seen.add(normalized)
            result.append(normalized)
    return result
```| Example requirement | Expected behavior |
|---|---|
| Empty or whitespace-only values | Return an empty list when no labels remain. |
| Case and outer whitespace | [" Teal "] becomes ["teal"]. |
| First occurrence order | ["b", "A", "b", "C", "a"] becomes ["b", "a", "c"]. |
| Internal whitespace | "One Two" (one space) and "One Two" (two spaces) remain distinct. |
| Numeric labels | "007" remains a string and differs from "7". |
| Input preservation | The original list stays unchanged after the call. |
The complete fixture also covers the supplied mixed example, case duplicates and tabs/newlines at the edges. Before collecting answers, we checked that the evaluator accepted correct implementations and rejected faulty results, the wrong return shape and input mutation.
Is Qwen better than ChatGPT for coding? These completed functions do not separate them. This was one small helper, not a repository change, debugging session or coding-agent comparison. For a different workflow involving project files, see our Qwen Code guide.
Which should you try?
| Your immediate need | What our evidence supports | Next step |
|---|---|---|
| Short writing, explicit extraction or a small calculation | Every completed answer passed these narrow checks. There is no content-quality winner here. | Try either official chat on a small task you can verify; compare the facts and constraints, not fluency alone. |
| An answer without a follow-up or retry | ChatGPT completed all eight requests in this session. Qwen supplied a complete answer for seven of eight requests; one of those seven also displayed a blank alternative. | Treat that as this session’s experience; keep a fallback for time-sensitive work rather than assuming stable availability. |
| A Python helper | All four completed functions passed our 10 checks; Qwen’s second request was only partially complete. | Write your own expected outputs and edge cases before accepting generated code. |
| Files, images or browsing | Not compared. ChatGPT also displayed a temporary tool limit during collection. | Check access in your own account. Our Qwen PDF guide and image-generation guide are separate single-app tests. |
| An API or downloadable Qwen model | Consumer-chat results do not establish performance or cost for a specific deployment. | Use the Qwen models, API or local-run guide for that decision. |
For a useful comparison of your own, write one prompt and its success criteria first, send it in fresh chats, keep every first answer and check it against an independent reference. Treat improvements after follow-up prompts as a separate test. Use material you are authorised to share with both providers.
Method, full answers and limits
We froze the exact prompts, expected outputs, checks and run order before inference; the validated offline baseline is dated 01:00:42 UTC on September 22, 2026. Each app received two attempts per task in fresh conversations. The task order changed between rounds, and each app went first once per task. This was a planned sequence, not randomised or blinded testing.
No response was regenerated, corrected or fed to the other app. Our rule for unsolicited alternatives was fixed beforehand: preserve every slot and award a full request pass only if all alternatives complete and meet the criteria. The two decisions to stop stalled outputs were later operational interventions and are recorded separately.
Most answers preserve the text supplied by the app’s response Copy control. One Qwen code alternative was captured from rendered code lines; display-only nonbreaking spaces were converted one-for-one to ordinary spaces and a Python fence was added for the text record. Its original displayed lines and code HTML are retained. That file is not a raw copied model response. Its one-block format was observed in the interface.
Read all prompts, 15 answers and blank-slot records (.txt)
Download the full test records (.zip) — frozen criteria, complete captured answers, observations, evaluations and the Python checker. Account details, private drafts and credentials are excluded.
We checked the email obligations and arithmetic, validated the JSON, and executed the inspected functions in a bounded local worker. This does not constitute an external human panel or a general security audit.
Limits: four prompts and two attempts do not establish broad accuracy, reliability or a model ranking. We did not compare paid plans, maximum context, multilingual work, long documents, image quality, browsing, thinking-on modes, coding agents, privacy policies or speed. The apps and account access can change, and hidden routing was not independently verifiable.
The observed official chat interfaces support the settings and session observations; our downloadable records support the test outcomes. We will revisit this comparison when material interface changes or reproducible corrections affect it. Send a correction with the task and supporting evidence.
Continue to the Qwen overview, Qwen vs DeepSeek test or earlier DeepSeek vs ChatGPT comparison. Those comparisons use different prompts and protocols; their results cannot be combined into a three-way ranking.