Independent comparison / Apps and named API models
DeepSeek vs Kimi: official app tests and ten API tasks
In three small tests of the official web apps, both DeepSeek and Kimi corrected a stale NASA claim and read the same chart accurately. Kimi also generated and revised a Word file; DeepSeek supplied accurate copy-ready text. Our separate ten-task API study found no overall winner and showed that hosting and output settings can change what users receive.
Choosing a chat app? Start with the three app tests and advice for your task. Building with an API? Start with the providers and settings we compared, then read the results and costs. The app trials and the 50 preserved API first responses are separate studies: an app result does not identify its backend model or predict a named API endpoint’s behavior.
By China AI Chat Team. Tested and source-checked September 24, 2026 (UTC). Research, collection and review were AI-assisted; see our methodology. ChinaAI is independent of DeepSeek, Moonshot AI and Together AI.
Which should you choose?
For the official web apps: both completed our NASA source check and chart reading. On the handout task, Kimi produced a revised DOCX while DeepSeek provided revised text to paste into Word. Choose Kimi if that observed file workflow is essential; use either app for a task you can verify. Account plan, region and changing product features can alter the route.
For an API: choose an exact model, host, mode and output cap before comparing answer quality. On our fixed text prompts, Kimi K3 through Together produced a final answer in all ten no-thinking requests. DeepSeek’s first-party non-thinking alias also did so in all ten, while Together’s DeepSeek V4 Pro endpoint returned no final text on three prompts under our 1,800-token cap. Do not treat those cross-provider counts as a reliability percentage. The outputs and the reporting of internal reasoning differ across services.
For cost-sensitive text integrations: Together’s listed rate for Kimi K3 was higher than its listed rate for DeepSeek V4 Pro 0813 at the time of review. Price alone cannot decide whether the more expensive endpoint produces enough value on your own tasks; a practical next step is to run a small, scored sample with your expected output lengths. See the exact listed rates and service boundaries.
Three real tasks in the official web apps
On September 24, 2026, we used signed-in sessions at DeepSeek Chat and Kimi. We sent one shared prompt per app for a NASA source check and a chart-image question. For the handout, we sent one shared prompt and then the same revision request in each original chat. That is six initial answers plus two same-chat revisions, separate from the API tests below. Neither app exposed an independently verifiable serving checkpoint.
| Reader job | DeepSeek Chat | Kimi | Useful distinction |
|---|---|---|---|
| Check a stale NASA claim | Correctly identified Artemis III as a planned 2027 Earth-orbit demonstration and Artemis IV as the first planned Artemis crewed lunar landing in 2028. Linked related NASA pages, though not the exact Artemis III URL requested. | Made the same correction and listed NASA pages. One table citation had a malformed text-fragment URL; clean source-list links were usable. | Verify the cited page itself before repeating a changing date. |
| Create and revise a handout | Said it could not attach a Word file in that chat. It supplied accurate copy-ready text and updated all six schedule times in the same conversation. | Generated original and revised DOCX files in the same chat. Both opened in the app’s Word preview; we checked the revised preview for the new times and unchanged details. | If the deliverable must be a DOCX, Kimi completed that app workflow on this account and date. |
| Read the same chart image | Found the 60-visit Q2-to-Q3 2026 fall, the 170-visit Q4 year-on-year difference and the provisional Q4 label. | Reported the same three findings from the identical uploaded image. | Both handled this small visual calculation; neither result establishes general image accuracy. |
Source check: the year and the mission both changed
The exact shared question challenged a claim that Artemis III would land astronauts on the Moon in 2026. NASA’s current Artemis III mission page and its June 2026 crew update support the correction: Artemis III is planned as a 2027 low-Earth-orbit test; Artemis IV is the first planned Artemis crewed lunar South Pole landing in 2028. Both apps rejected the wrong year and wrong mission. Kimi flagged a conflicting older NASA page variant; we relied on the current mission page and June release. Its malformed table citation is a reminder to inspect sources even when the answer sounds right.
Document task: a file versus text to paste
The fictional Harbor Library brief required a one-page handout for November 12, 2026, at East Hall, 18 Beacon Lane, with wheelchair access via the east entrance and questions sent to [email protected]. The first schedule ran from 09:30 check-in to 12:00 finish. The follow-up changed six times, from 10:00 check-in to 12:30 finish. Both apps retained the unchanged facts in their revised outputs and added no phone, parking or food instructions. Kimi produced two DOCX files; DeepSeek transparently gave copy-ready text. This is an observed artifact-workflow difference, not a prose-quality ranking.
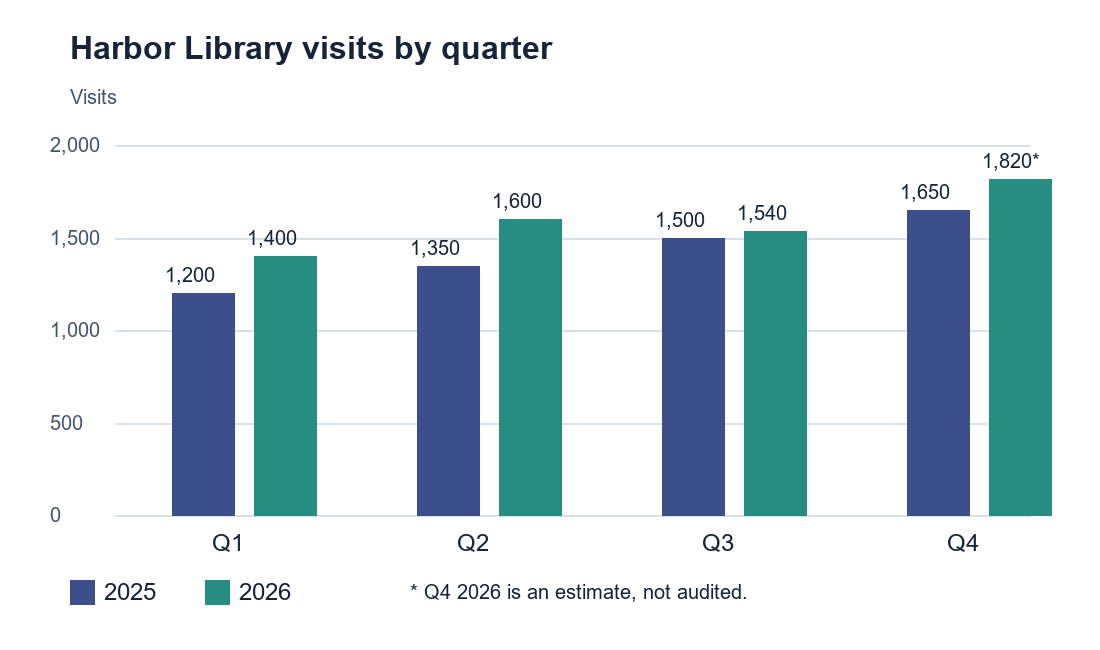
Full chart data for readers who cannot see the image: 2025 Q1 1,200; Q2 1,350; Q3 1,500; Q4 1,650. 2026 Q1 1,400; Q2 1,600; Q3 1,540; Q4 1,820 (estimate, not audited). Both first answers calculated the 60-visit Q3 fall and the 170-visit Q4 difference, preserved the estimate qualifier and invented no cause.
Download the frozen prompts, predeclared checks, chart and observation notes (.zip). This is a small reproducible record, not a transcript of private account chats or a benchmark dataset.
Official apps: choose a workflow, not just a model name
Kimi’s official products page lists its online workspace alongside Kimi Work and Kimi Code, and dedicated Slides, Docs, Sheets and Deep Research features. Those are meaningful routes if the desired output is a presentation, an editable document, a spreadsheet or a sourced research report. Our Kimi Slides, Docs, Sheets and Deep Research guides describe narrower hands-on workflows and their observed limits.
DeepSeek’s official site directs visitors to its chat and developer platform. If your job is to ask questions, inspect cited web results or work with a PDF in chat, follow the official route and our DeepSeek Search and PDF guides for tested steps. This comparison does not claim DeepSeek lacks features that Kimi lists, or that one app’s interface is better because an API response was better.
For either service, use a short non-sensitive sample first, check the output against the source, and then review the account’s data and plan settings. Access and quotas may change.
API study: which models and providers did we compare?
The API study used ten fictional text prompts across the configurations below. Read the provider, mode and output cap together: they affect which results can be compared. The app row shows where the separate web-app trials fit.
| Decision | DeepSeek | Kimi | Evidence here |
|---|---|---|---|
| Official web app | DeepSeek Chat | Kimi | Three dated matched workflows: NASA source check, handout and chart image; six initial answers and two document revisions. See app trials. |
| Named Together API endpoint | deepseek-ai/DeepSeek-V4-Pro-0813 | moonshotai/Kimi-K3 | Ten identical text prompts at high reasoning, then the same ten in a post-hoc no-thinking sensitivity run. |
| First-party API | deepseek-v4-pro at DeepSeek’s API | Not run in this comparison | A separate ten-prompt DeepSeek diagnostic with thinking disabled; not a matched first-party-vs-first-party trial. |
DeepSeek’s change log, rechecked September 26, 2026, says Pro API service continues beyond September 14. Its current model table maps deepseek-v4-pro to V4-Pro-0813. This clarifies the earlier September 10 announcement of a planned switch to V4.1 Flash. Our September 24 response returned the Pro alias; it did not expose a verifiable checkpoint hash or establish that its serving stack matches Together’s. The official chat apps may use other model versions and tools.
API results: what the ten tasks showed
We fixed two prompts per category before testing. The most interpretable text-answer comparison below uses Kimi K3 on Together with no-thinking requested and DeepSeek’s first-party alias with thinking disabled, both capped at 1,800 output tokens. Those are different providers; the table describes observed answers, not controlled model performance. We also publish the same-host Together lanes, including every blank final answer, in the full records.
On a narrow screen, swipe the table to compare all columns.
| Task pair | What Kimi returned | What first-party DeepSeek returned | Useful distinction |
|---|---|---|---|
| Reconcile changing source notices | Correct shuttle facts; gallery answer omitted the requested absent-email line. | Correct shuttle facts and included “Not stated” for the gallery email. | Both tracked later corrections; the one omission matters if a missing field must appear in the output. |
| Two multi-step invoices | Both correct final amounts: £229.55 and £1,131.84. | Both correct final amounts: £229.55 and £1,131.84. | Both respected cancellations, returns, fees and credits in these examples. Verify financial outputs yourself. |
| Two Python repairs | CSV parser passed 12 of 13 local checks; revision counter passed 8 of 8. | CSV parser passed 13 of 13; revision counter passed 8 of 8. The latter missed the requested code-fence format. | Kimi’s CSV function failed one invalid-quote rejection. DeepSeek’s one format miss did not affect those eight functional checks. |
| Two constrained public notices | Met both 90–120-word briefs and preserved required facts. | Met both 90–120-word briefs and preserved required facts. | DeepSeek’s library notice was easier to scan; that is an editorial judgment, not a measured quality score. |
| Two Chinese/English translations | Preserved core meaning and numbers, with small terminology choices to review. | Preserved core meaning and numbers, with different small terminology choices to review. | Neither response justified a general multilingual winner. Check proper names and service terms. |
What would have changed a real user’s answer?
In the gallery notices, the prompt explicitly said to mark an absent contact email as “Not stated.” Kimi did not include that field, even though its other dated facts were right. This is a failure of completeness rather than a fabricated email. In the CSV repair, Kimi’s function accepted the malformed input "a"x,b; the frozen task requirement was to reject characters after a closing quote. First-party DeepSeek’s function rejected it. These are inspectable differences, unlike a vague impression that one answer “sounds smarter.”
The two invoice prompts are deliberately fictional and have independently calculated outcomes. Both APIs reached the same correct totals, but the catering fee’s third decimal did not distinguish half-up from half-even rounding; that task should not be cited as evidence of rounding-mode mastery. The notices and translations likewise are small first-answer examples, not general accuracy rates.
Why the DeepSeek hosting result needs care
Our first frozen lane asked the Together-hosted DeepSeek V4 Pro 0813 and Together-hosted Kimi K3 to answer all ten prompts at high reasoning with a 3,000-output-token cap. Kimi returned final text on all ten. DeepSeek returned final text on seven, while the shuttle and both code tasks exhausted the cap without any final answer. We kept those three empty finals in the published records.
After seeing that, we froze a second plan and reran all ten prompts for both Together endpoints, this time requesting no-thinking and allowing 1,800 output tokens. Kimi returned final text on all ten again. Together’s DeepSeek endpoint still reported substantial reasoning-token use and no final text on the same three tasks. Its English-to-Chinese answer also stopped at the cap, but contained partial final text. We then froze a third plan and ran the ten prompts on DeepSeek’s first-party API with thinking disabled. That service returned final text on all ten. These were post-hoc diagnostic lanes, not pre-planned repeated trials; the second lane changed both requested mode and cap, so it does not isolate one cause.
The actionable lesson is to test the actual host and configuration you intend to deploy. A blank final answer at a token cap can reflect how reasoning, mode controls and output budgets interact. It does not establish that a model cannot solve the task. Conversely, one complete answer from a different host does not prove every future call will complete.
API choice and a transparent price example
On September 24, 2026, Together listed moonshotai/Kimi-K3 at $3 per million uncached input tokens and $15 per million output tokens. It listed deepseek-ai/DeepSeek-V4-Pro-0813 at $1.32 and $3.96 respectively. At those list rates, a hypothetical one million uncached input tokens plus one million output tokens would be $18.00 for Kimi and $5.28 for DeepSeek. This is simple rate arithmetic, not our actual test bill or a comparison of consumer subscriptions. Cached inputs, provider discounts, internal reasoning output and changed rates can alter a real invoice. Check the live Kimi and DeepSeek cards before buying capacity.
Together lists Kimi K3 with text and image input; it lists this DeepSeek V4 Pro endpoint as text input. That is a provider-endpoint distinction, not a claim about everything either company’s apps or model family can do. DeepSeek’s first-party API rates and peak/off-peak rules are separate from Together’s pricing. See our DeepSeek API, Kimi API, DeepSeek pricing and Kimi pricing guides before choosing a service.
If you are evaluating your own workload, decide in advance how you will judge completeness, factual support, format, edge cases and spend. Test the same prompt and output requirement on the exact provider configuration you would ship. Keep blank or incomplete results, and allow enough output tokens for a reasoning model.
Method, complete first answers and limits
We froze ten prompts and success criteria before the first request: two source-update tasks, two invoices, two Python repairs, two short public notices and two translations. Every prompt used fictional material. Across the API configurations, we preserved 50 first responses, with one request per prompt in each configuration, no tools and no quality retries. The two supplemental test plans were chosen after the initial results; see how the host, mode and output cap changed.
Protocol checksum and API settings
The frozen protocol’s SHA-256 is 62ce64c325c53fdc. The original Together high-reasoning lane used both named endpoints with reasoning_effort=high and a 3,000-output-token cap. After its results, two supplemental plans were frozen before their respective calls: a no-thinking-requested Together lane for both models and a first-party DeepSeek lane with thinking disabled, each capped at 1,800 output tokens.
We independently ran the returned Python functions against local checks written during evaluation, after the first requests; the functional requirements in the prompts were frozen beforehand, but the executable checker itself was not preregistered. Reviewers separately inspected the source facts, arithmetic, word limits and bilingual meaning. These AI-assisted reviews are our internal checks, not a human panel or external expert endorsement. The publicly downloadable package contains exact prompts, full final answers, empty finals, reported model names, settings, finish reasons, token usage and code-check results. Private request identifiers, credentials and reasoning traces are excluded.
Download all 50 first responses and protocol (.zip)
Limits that matter: Ten distinct fictional text prompts with one first response per configuration are too few to calculate a general accuracy or reliability rate. The lanes differ in host, mode and output cap; the first-party alias did not expose the exact backend checkpoint. The separate app trials above tested one source check with browsing, one document revision and one chart image. They did not test PDFs, long-context retrieval, a real repository, safety, privacy, uptime or speed; neither the app nor API samples establish general performance. No result here predicts performance on your private files or production traffic. We did not regenerate a failure to make the table look better.
For the wider context, visit the DeepSeek overview, Kimi overview or other comparisons. We will update this page when a material provider mode, model route, feature or price changes, or when a reproducible correction affects a finding. Send a correction with the affected prompt and evidence.