Qwen / Local text generation on Windows
Run Qwen locally on Windows with Ollama
To run Qwen locally on Windows, download Ollama and a local Qwen model, start the runtime, then send it a prompt on your own computer. This guide follows the standalone Windows version of Ollama and the native qwen3.5:9b package. A hosted API account or API key is not required for this route.
On our Intel Core i7-14700 desktop, the package ran entirely on the CPU at a 4,096-token context. We tried three distinct prompts, each three times: JSON extraction passed on every repeat, the summary omitted required advice every time, and the arithmetic answer was wrong every time. These are three task examples repeated for observation and timing, not nine independent quality cases. The setup, original answers and timings follow.
By China AI Chat Team. Sources checked September 21, 2026. Tested September 21, 2026. See how we research.
Before you start
This is a Windows text-generation walkthrough. It does not install Qwen Code, generate images or expose a model server to the internet. If you are deciding between the assistant, hosted access and downloaded weights, start with our Qwen overview or Qwen models guide.
You need a supported Windows computer, internet access for the initial downloads and enough local disk space. Ollama's Windows documentation lists Windows 10 22H2 or newer. Our machine’s exact configuration is in the results section; it is not a minimum specification.
Allow roughly 20 GB of free disk space for this walkthrough’s runtime, model, archive and temporary files. That is working headroom, not a measured minimum. Avoid putting the model directory in a small or automatically synchronized folder.
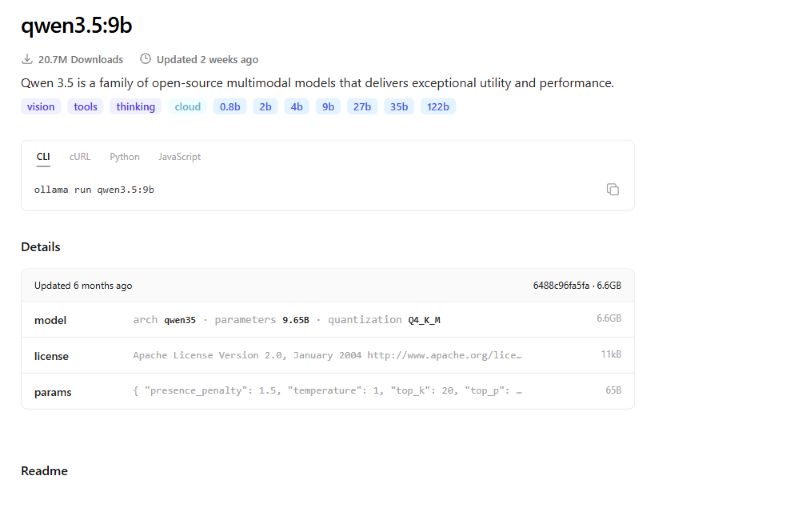
The official qwen3.5:9b package was listed at 6.6 GB, with Q4_K_M quantization. Quantization reduces the precision used to store model weights; the downloaded size does not tell you the complete memory needed while generating an answer. The 9b label identifies our selected size, not the newest or best Qwen model for every task.
If this candidate is too slow for your use, the official qwen3.5:4b package, listed at 3.4 GB, is a smaller option to assess. We did not test 4B: the 9B runtime completed our requests without reaching the predeclared latency or timeout thresholds. Large RAM capacity alone is not a reason to start with a much larger model.
Set up the standalone Windows runtime
1. Download and extract Ollama
Our controlled setup uses Ollama 0.34.2 from the official release. Download ollama-windows-amd64.zip for a 64-bit x86 Windows machine and extract it into a local folder. This is the standalone archive route; it is different from running the graphical OllamaSetup.exe installer. ARM Windows needs a different build.
The archive we downloaded was 1,460,928,014 bytes. Its SHA-256 matched the release’s published digest, and Windows reported a valid Ollama Inc. signature on ollama.exe. Open PowerShell in the folder containing the downloaded ZIP, then check it with:
Get-FileHash -Algorithm SHA256 -LiteralPath '.\ollama-windows-amd64.zip'For that exact 0.34.2 archive, the expected SHA-256 is:
8f3fd071a2a2f9497b562f43502c77c2b701a99d1ee5dfda28da8c786373063bA different release has a different checksum. Compare it with its own official release record; do not use this hash to approve an unrelated download.
2. Start a local server
Open PowerShell in the extracted folder, where ollama.exe is visible. Use this first window for the server:
$env:OLLAMA_MODELS = Join-Path (Get-Location) 'models'
$env:OLLAMA_HOST = '127.0.0.1:11434'
$env:OLLAMA_NO_CLOUD = '1'
$env:OLLAMA_NUM_PARALLEL = '1'
$env:OLLAMA_MAX_LOADED_MODELS = '1'
$env:OLLAMA_VULKAN = '0'
.\ollama.exe serve
Leave that window open. The local address connects programs on this computer to Ollama. The model directory is the models folder inside your chosen runtime folder. These environment settings belong to this PowerShell process; repeat them when starting a new server session. See Ollama's configuration FAQ.
The commands limit the server to one loaded model and one parallel request. We also disabled the Vulkan backend for our measurement. That switch alone does not disable every other GPU backend; check actual placement with ollama ps below. If your goal is accelerated inference, use the GPU-specific setup documentation for your hardware rather than treating our CPU result as its expected speed.
If another Ollama server is already using port 11434, do not start a second copy or stop an unrelated process. Decide which existing setup you intend to use and check its configuration first. The standalone route does not require installing a Windows service.
3. Download and inspect the exact model
Open a second PowerShell window in the same extracted folder, then run:
$env:OLLAMA_HOST = '127.0.0.1:11434'
.\ollama.exe pull qwen3.5:9b
.\ollama.exe list
.\ollama.exe show qwen3.5:9b
Keep the size suffix: qwen3.5:9b selects the native library package used here. Do not substitute a cloud-tagged model or a separately packaged GGUF and assume the same instructions apply. Wait for the pull to finish before sending the first prompt.
Our completed download resolved to model ID 6488c96fa5fa, with qwen35 architecture and Q4_K_M quantization. ollama list and ollama show both completed successfully. The full manifest digest is in the downloadable record:
6488c96fa5faab64bb65cbd30d4289e20e6130ef535a93ef9a49f42eda893ea7In our test, the package was downloaded through Ollama’s native pull API. The CLI pull syntax above was checked against the installed runtime’s help; the inspection commands were executed. A model tag can later resolve to a different package, so compare the recorded identity when repeating the test.
Generate your first local answer
Keep the server running. In the second PowerShell window, send a short, bounded request:
$request = @{
    model = 'qwen3.5:9b'
    prompt = 'Reply with exactly: Local model ready.'
    think = $false
    stream = $false
    keep_alive = '5m'
    options = @{
        num_ctx = 4096
        num_predict = 128
        num_thread = 8
        temperature = 0
        seed = 42
    }
} | ConvertTo-Json -Depth 5

$answer = Invoke-RestMethod -Uri 'http://127.0.0.1:11434/api/generate' `
    -Method Post -ContentType 'application/json' -Body $request -TimeoutSec 180
$answer.response
This uses Ollama’s local generation API. think=false disables thinking mode for this demonstration. num_predict=128 caps the generated output, while num_ctx=4096 sets a separate context window. They are different limits. Eight inference threads are our chosen setting for the active desktop, not an optimal value for every CPU.
The PowerShell request returned this exact answer:
Local model ready.Run the block directly in PowerShell. This nonstreaming example returns the completed answer; it does not measure time to first token.
To ask your own question, replace the prompt value and resend the request. Start with a short task, such as extracting fields from a paragraph you wrote. Each example here sends a fresh prompt without conversation history; keeping the model loaded does not add previous questions to that request.
Then inspect where the model is running:
.\ollama.exe psRead the actual PROCESSOR and context columns. A detected graphics adapter is not proof that inference is using it. GPU behavior depends on the backend and supported hardware; consult the current GPU documentation for your device.
Stop the model and manage its files
When you finish, use the second PowerShell window in the extracted runtime folder to unload this model and check the loaded-model list:
.\ollama.exe stop qwen3.5:9b
.\ollama.exe ps
Check that qwen3.5:9b no longer appears in the ps output. Unloading keeps the downloaded files so you can use the model again. In the first PowerShell window, press Ctrl+C to stop the foreground server you started. A separately installed background Ollama application is a different process; closing a command window does not necessarily stop that application.
In our test, this sequence unloaded the model: ollama ps displayed only its header, and the local loaded-model API returned an empty list.
The model files for the setup above are in your chosen runtime folder’s models directory. Do not delete other models or a general Windows temporary directory to free space. If you later want to remove this specific downloaded model, use Ollama’s model-management commands after checking the selected model name.
Troubleshooting the Windows workflow
| What you see | What to check |
|---|---|
ollama is not recognized | This standalone archive does not need to be on PATH. Open PowerShell in the extracted directory and use .\ollama.exe. |
| Connection refused | The first server window may be closed, startup may have failed, or the host/port may differ. Check that window before sending another prompt. |
| Address already in use | Another process owns the port. Identify the intended Ollama setup; do not indiscriminately kill processes or launch competing servers. |
| Pull fails or remains incomplete | Check the model tag, available disk space and download connection. Read the exact error; an incomplete pull is not proof that the model cannot run on your CPU. |
| Model or architecture not supported | Check the installed runtime version and the native library entry. Instructions for a third-party GGUF or separate vision file may require a different import route. |
| The answer ends too soon | Inspect the completion reason. An output limit is different from an empty model response or transport failure. Increase the limit deliberately for a larger task; do not remove it blindly. |
| Long wait or memory pressure | Start with a short prompt and modest context. Check actual processor placement, other running work and model size. A smaller package is a candidate to test, not a guaranteed speed figure. |
| GPU exists but processing is on CPU | Check the supported backend/driver combination and ollama ps. Integrated shared memory is not dedicated graphics-card VRAM. |
If the pull repeatedly reports stalled parts, Ollama’s downloader supports resuming from saved partial progress. Leave the server window open, cancel only the pull command with Ctrl+C, allow it to stop, then rerun the same pull command against the same model directory. Keep the partial files. Resume support does not guarantee that every in-flight byte will be retained. See the 0.34.2 downloader implementation.
If startup fails with a profile-directory error, read the message in the server window and check the location against Ollama’s Windows documentation. Our test used a separate project profile; that was a condition of the test environment, not a required step for this walkthrough.
Does local Qwen require a paid API?
This local downloaded-model route does not use a hosted inference API or need a hosted API key. Downloads, disk space, electricity and computer time still have costs. For provider-hosted access instead, use the separate Qwen API guide.
Is this the same as proving it works offline?
No. The setup uses a local model and disables Ollama cloud features, but we do not disconnect the computer from the network. Downloads need internet access. A network-isolation test and a review of any extra frontend or tool are separate checks; do not infer a universal privacy guarantee from the word “local.”
Can I connect this to Qwen Code?
A working local runtime is only one prerequisite. Our Qwen Code guide explains the coding-agent client and its separate provider-backed test. This 4K-context text experiment does not validate a local Qwen Code connection, tool use or a long-context repository task.
What happened on our Windows machine
The local workflow ran successfully, but only the extraction task met every answer criterion. The summary was incomplete and the arithmetic answer was wrong in each repetition. Successful completion and a short wait are separate from answer quality.
| Task | Result in all three repetitions | What to check yourself |
|---|---|---|
| JSON extraction | Met the required keys, values, types and JSON format. | Parse the output and compare every field with the source. |
| Summary | Omitted the advice to bring water, although the other facts and required format were preserved. | Check practical instructions as well as names, dates and numbers. |
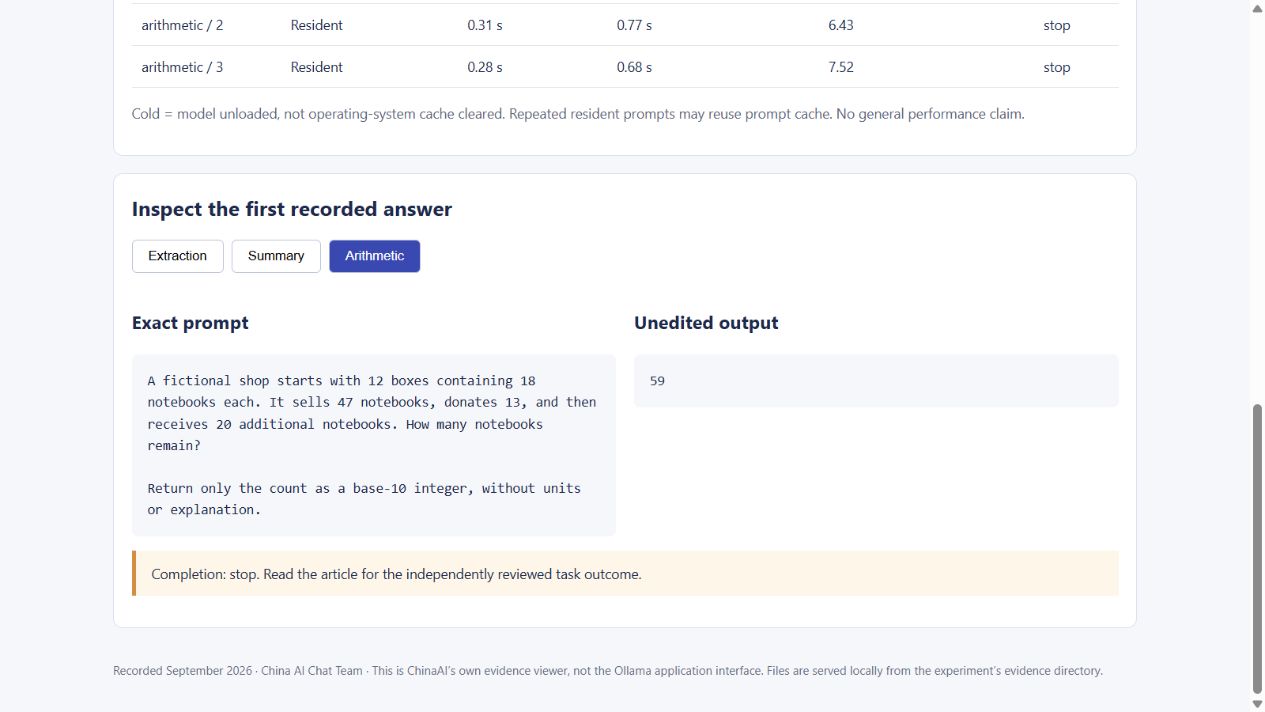
| Arithmetic | Returned 59; the correct count is 176. | Recalculate: 12 × 18 − 47 − 13 + 20 = 176. |
These are three distinct tasks, each repeated three times with the same settings. They do not establish general accuracy or predict performance on a 16 GB laptop, large documents, vision tasks or coding-agent work.
| Item | Recorded configuration |
|---|---|
| CPU | Intel Core i7-14700; 28 logical processors exposed |
| Memory | 104.0 GiB installed; 103.24 GiB available to Windows as total usable RAM—not free RAM |
| Windows | Build 26200, release 25H2 |
| Runtime and package | Ollama 0.34.2; qwen3.5:9b; Q4_K_M |
| Actual placement | ollama ps: 100% CPU, 4,096 context |
| Request limits | 4,096 context tokens; 256 maximum generated tokens per task; thinking disabled |
| CPU and concurrency settings | Eight inference threads; one request and one loaded model at a time; Vulkan disabled |
| Sampling | Temperature 0 and seed 42; native defaults retained for presence penalty 1.5, top-k 20 and top-p 0.95 |
| Largest sampled working-set sum | 6.55 GiB across the owned server and child processes; measurement limits below |
These are observations from a machine with unusually large RAM capacity, not minimum hardware requirements. Our sampling settings were fixed for this small experiment; we did not optimize them or compare thinking modes.
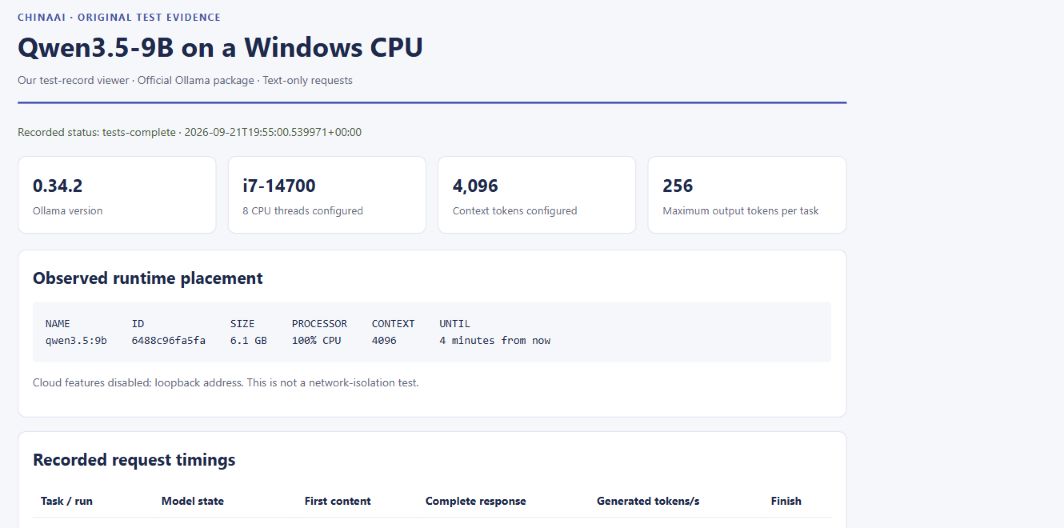
For example, the resident extraction requests started showing text after about 0.26–0.27 seconds, but took 16.36–16.54 seconds to finish the JSON. Generation rate for the longer extraction and summary responses ranged from 4.92 to 4.98 tokens/second. The raw CSV includes load time, token counts, generation rates and memory figures for every request.
The 6.55 GiB figure above is a sampled sum of process working sets. It can count shared pages twice and miss a peak, so it is not a minimum-RAM requirement. The desktop was in active use, and repeated prompts may benefit from caching as well as an already loaded model.
See all nine timings and completion records
All nine measured requests
| Task / run | Model state | First content (s) | Full response (s) | Criterion met? |
|---|---|---|---|---|
| JSON extraction / 1 | Unloaded | 7.86 | 24.00 | Yes |
| JSON extraction / 2 | Resident | 0.26 | 16.36 | Yes |
| JSON extraction / 3 | Resident | 0.27 | 16.54 | Yes |
| Summary / 1 | Unloaded | 8.72 | 23.76 | No: advice omitted |
| Summary / 2 | Resident | 0.27 | 15.14 | No: advice omitted |
| Summary / 3 | Resident | 0.26 | 15.11 | No: advice omitted |
| Arithmetic / 1 | Unloaded | 7.20 | 7.60 | No: wrong count |
| Arithmetic / 2 | Resident | 0.31 | 0.77 | No: wrong count |
| Arithmetic / 3 | Resident | 0.28 | 0.68 | No: wrong count |
All nine requests ended with done_reason=stop, with no recorded transport error. They generated 80 tokens for extraction, 74 for summary and three for arithmetic—each below the 256-token limit. The two preliminary five-token readiness replies took 6.95 and 1.11 seconds; they are excluded from the table.
Read the exact prompts and unedited answers
Exact prompts and first answers
The first answer for each task is reproduced below. Both resident repetitions produced the same text as that task’s first response.
JSON extraction
Exact prompt:
Extract only the facts below. Return one JSON object with exactly these keys: event, date, time, city, capacity, ticket_gbp, contact_email. Use strings for event/date/time/city, numbers for capacity/ticket_gbp, and null for missing information. No Markdown or additional text.

Fictional event: Harbor Code Clinic.
Date: 14 October 2026. Start time: 18:30.
City: Bristol. Maximum attendance: 24 people.
Standard ticket: GBP 12. No contact email has been published.
Use YYYY-MM-DD for date and HH:MM for time.
First unedited answer:
{
  "event": "Harbor Code Clinic",
  "date": "2026-10-14",
  "time": "18:30",
  "city": "Bristol",
  "capacity": 24,
  "ticket_gbp": 12,
  "contact_email": null
}
Result: met the criterion in all three runs. The JSON had exactly the required fields, values and types, including null for the missing email. We checked valid JSON and duplicate keys as well as the extracted facts.
Summary
Exact prompt:
Summarize this fictional update in exactly three bullets, beginning each with "- ". Use one bullet each for opening, completed work, and remaining restrictions. Each bullet must contain at most 25 words. Include the stated numbers and preserve uncertainty. Add no facts.

Riverside Pocket Park opens on 4 October 2026, with daily opening hours of 07:00–21:00. Phase one added a 2 km walking path and 30 trees. The playground remains closed pending inspection; no reopening date has been announced. Drinking fountains are not installed, so visitors should bring water.
First unedited answer:
- Riverside Pocket Park opens October 4, 2026, with daily hours from 07:00 to 21:00.
- Phase one added a 2 km walking path and 30 trees.
- The playground remains closed pending inspection; no reopening date has been announced. Drinking fountains are not installed.
Result: incomplete in all three runs. It omitted the source’s advice to bring water, so it failed our predeclared completeness criterion despite preserving the other facts and required format.
Arithmetic
Exact prompt:
A fictional shop starts with 12 boxes containing 18 notebooks each. It sells 47 notebooks, donates 13, and then receives 20 additional notebooks. How many notebooks remain?

Return only the count as a base-10 integer, without units or explanation.
First unedited answer:
59Result: wrong in all three runs. The expected count is 176: 12 × 18 − 47 − 13 + 20. The model returned 59. This is one short, fixed non-thinking task; it does not establish a general mathematics score. Verify numbers before using them.
Test method, measurement limits and setup conditions
How the small experiment works
We define three fictional tasks and their success criteria before sending any test request: exact JSON extraction, a source-grounded three-bullet summary and integer arithmetic. Each task is sent as a fresh request three times: once after unloading the model, then twice while it remains resident. No earlier conversation is included.
Each prompt was repeated with temperature 0 and seed 42. Those repetitions help describe timing and consistency under this configuration; they do not expand coverage to nine different quality cases. “Cold” means model unloaded, not a cleared Windows file cache. “Warm” means model resident. Prompt caching can also speed up identical requests, so a faster repeat cannot be attributed entirely to avoiding a model load.
The measurement requests use streaming, with client time to first non-empty response content recorded separately from time to completion. Generation rate is Ollama’s generated-token count divided by its reported generation duration. It does not include every part of the wait. The separate PowerShell example above uses nonstreaming output and is excluded from these timing comparisons.
The memory sampler observes the launched server and its descendants at nominal 250-millisecond intervals. Its figure is a sampled sum of process working sets; shared pages may be counted more than once and an unsampled peak may be missed. It is not a model’s minimum RAM requirement or a complete account of Windows memory use.
The computer remains an active desktop, not a dedicated benchmark machine. These short tasks do not establish general model accuracy, performance on a 16 GB laptop, large-document capacity, vision quality or coding-agent reliability.
Setup conditions recorded during the test
Our initial attempt to launch the first-answer PowerShell example as a .ps1 file was blocked by the local script-file restriction; running the commands directly in PowerShell then worked. We made no execution-policy change. The failed launch is retained in the records and did not send an inference request. This nonstreaming example returns the completed answer; it does not measure time to first token.
Our test harness initially lacked permission to create Ollama’s default profile directory. We used a separate profile inside the test project without changing account-wide permissions. That was a setup problem before inference, not a Qwen model failure. Ordinary standalone installations normally use Ollama’s documented profile location.
If the pull repeatedly reports stalled parts, Ollama’s downloader supports resuming from saved partial progress. Leave the server window open, cancel only the pull command with Ctrl+C, allow it to stop, then rerun the same pull command against the same model directory. Keep the partial files. We reset the connection twice during our API-driven download; the checkpoints retained 2.97 GB, then 4.77 GB. This does not guarantee that every in-flight byte will be retained in another interruption. The behavior is documented in the 0.34.2 downloader implementation.
Read the complete records as plain text (TXT, 187 KB), or download the original experiment records and method notes (ZIP, 48 KB). The archive includes the frozen prompts and criteria, all nine raw responses, two readiness checks, model identity, per-request metrics, answer review and walkthrough verification. Start with README.md; the included measurement code is for inspection and requires the original project layout to run. The archive contains no model binaries or API credentials. A private script-file path in the blocked-launch record is explicitly redacted; the model answers are unedited.
For a ready-to-run check of the saved results, download the standalone offline evidence checker (ZIP, 32 KB). Extract it and run python check_saved_qwen.py with Python 3.9 or later. It checks the nine saved requests, original mechanical scores and timing calculations using only Python’s standard library. It makes no model calls. A successful record check means the files are consistent, not that every answer was correct; summary meaning still needs the included written review.
ChinaAI is independent of Qwen, Alibaba and Ollama. Send a correction with the affected command, runtime/model version and a reproducible example. Changes to the runtime, native model tag, download packaging or observed behavior trigger a review; the original dated results remain identifiable.