DeepSeek / Local Windows walkthrough
Run DeepSeek R1 locally on Windows with Ollama
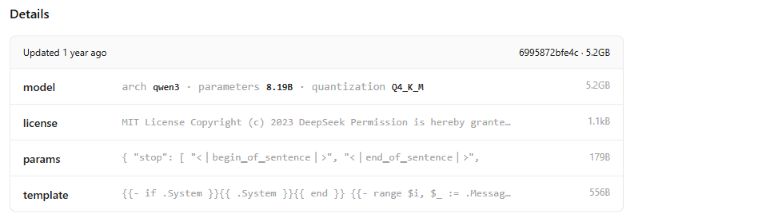
You can run a downloadable DeepSeek R1 distill on your Windows computer with Ollama, without a DeepSeek API key. This guide uses the exact deepseek-r1:8b-0528-qwen3-q4_K_M package: an Ollama quantization of DeepSeek-R1-0528-Qwen3-8B. It is a smaller Qwen3-based model trained with reasoning distilled from R1-0528, not the full R1 model. This guide does not identify or test the model serving DeepSeek Chat.
In our first three local requests, this small DeepSeek R1 distill gave the correct discounted total, but it did not obey the exact output format for JSON extraction and used stronger wording than the source in a short summary. It ran entirely on our CPU and the final answers took noticeably longer than the first thinking text. Use the guide to try it yourself, then check the final answer rather than assuming a fluent response is correct.
By China AI Chat Team · Official sources reviewed September 23, 2026 · Local experiment September 23, 2026 (Africa/Cairo; raw records use UTC) · How we research
Know which model you are downloading
The official Ollama package entry lists 5.2 GB, Q4_K_M quantization and Qwen3 architecture. The download-size label is not its peak running memory or a minimum-RAM requirement. The entry’s advertised 128K context is not the context allocated or tested here; our requests used 4,096 tokens. The exact local file size and sampled process memory are reported below.
Ollama’s Windows documentation lists Windows 10 22H2 or newer and at least 4 GB for its binary installation, with model storage in addition. Allow working space for the Ollama app, this model and temporary downloads; the standalone ZIP route below also needs room for its archive and extracted runtime. Our computer’s 104 GiB installed memory is a test condition, not advice that your PC needs 104 GiB.
Pick the route you actually have: Ollama’s normal Windows installer runs a background application and puts ollama on your terminal’s path. We tested its separate standalone ZIP/foreground-server route, not the installer. If you already have an Ollama service, check its configuration and use that instance deliberately; do not start a second server on its port or stop an unrelated process.
Names matter here. The unsuffixed deepseek-r1 and 8b aliases currently point to the 0528 Qwen3-based 8B package, but aliases may change. Ollama also lists an older, Llama-based 8B distill under a different tag. The explicit tag and recorded manifest below identify our package. See our DeepSeek models guide for the wider release and license map.
Simpler Windows setup: install Ollama and run the exact model
Documented route, not our measured test: Ollama recommends its normal Windows installer for most users. The steps in this section follow Ollama’s Windows guide, CLI commands and the exact model entry. We tested the separate standalone ZIP route in the next section, so our recorded answer quality, timing and memory figures do not measure this installer route.
- Install Ollama. Download
OllamaSetup.exefrom Ollama’s official Windows download page and complete its installer. Let the Ollama background app start. If you already use Ollama, check your existing installation before installing a second copy. - Open a new PowerShell window. The installer makes
ollamaavailable on your terminal path. Check withollama --version; if Windows does not recognize it, reopen PowerShell after installation. - Run the exact package. Enter the command below. Ollama downloads the named package if needed and opens an interactive chat. The model entry lists a 5.2 GB download; this is not a minimum-RAM figure.
ollama run deepseek-r1:8b-0528-qwen3-q4_K_M- Ask and check one small question. For example, ask What is 8 + 3? Reply with only the number. That is a suggested first check, not a prompt we tested through the installer. Inspect the final answer yourself. In another PowerShell window,
ollama psshows which model is loaded. - Leave the chat and unload deliberately. Type
/byeto exit the interactive session. Runollama stop deepseek-r1:8b-0528-qwen3-q4_K_Mif you want to unload that model, then checkollama ps. Exiting chat does not necessarily stop the background Ollama app. Do not run a secondollama serveon its occupied port.
The installed-app route uses ollama. The independently tested route below uses .\ollama.exe from a standalone ZIP and starts its own foreground server. Choose one route for a first attempt rather than mixing their server and model-directory settings.
Our tested route: set up the standalone Ollama runtime
1. Download and verify Ollama
For the measured route, we reused the official Ollama 0.34.2 ollama-windows-amd64.zip from its release page. The archive was independently verified on this same computer on September 21: SHA-256 8f3fd071a2a2f9497b562f43502c77c2b701a99d1ee5dfda28da8c786373063b, with a valid Ollama Inc. Windows signature on ollama.exe. Check your own downloaded ZIP against its release’s digest; a different release will have a different hash.
Extract it into a local folder with room for model files. Open PowerShell window 1 inside that extracted folder. This example keeps models in a models subfolder, binds only to your computer and disables Ollama cloud features:
$env:OLLAMA_MODELS = Join-Path (Get-Location) 'models'
$env:OLLAMA_HOST = '127.0.0.1:11434'
$env:OLLAMA_NO_CLOUD = '1'
$env:OLLAMA_NUM_PARALLEL = '1'
$env:OLLAMA_MAX_LOADED_MODELS = '1'
.\ollama.exe serve
Leave window 1 open. Our isolated experiment used port 11435 and a separate project-owned model directory so it would not change a pre-existing Ollama setup. The commands above use Ollama’s normal 11434 port for a reader starting a fresh instance. The environment settings apply to the server window you started. Ollama’s FAQ documents the loopback address, model directory, cloud switch and loaded-model checks. This is local inference, not a test of complete network isolation.
2. Pull and inspect the exact DeepSeek package
Open PowerShell window 2 in the same extracted folder. Point it to window 1’s host, then pull and inspect the explicit package:
$env:OLLAMA_HOST = '127.0.0.1:11434'
.\ollama.exe pull deepseek-r1:8b-0528-qwen3-q4_K_M
.\ollama.exe list
.\ollama.exe show deepseek-r1:8b-0528-qwen3-q4_K_M
Wait for a successful pull before generating text. If it fails, read the error and keep the partial files; a failed download is not a model answer. Our completed pull resolved to manifest SHA-256 6995872bfe4c521a67b32da386cd21d5c6e819b6e0d62f79f64ec83be99f5763. The registry displays its short prefix as 6995872bfe4c; this manifest identity differs from the model weight-layer digest. A tag may later point to new bytes, so check the identity if you want to reproduce our dated results.
Download recovery in our test
Our transfer was interrupted. Before inference, we recovered the weight file from Ollama’s official registry with a resumable download, verified its full SHA-256, and then completed the exact-tag Ollama pull. The public records document this setup recovery; it was not an answer retry. A reader using the normal pull command does not need our recovery script.
Get a first local answer and check completion
If you chose the installer route above, ollama run deepseek-r1:8b-0528-qwen3-q4_K_M opens your first interactive session. From the extracted standalone ZIP folder, the corresponding command is .\ollama.exe run deepseek-r1:8b-0528-qwen3-q4_K_M. Our measured tasks instead used Ollama’s local generation endpoint to fix the context, output limit and sampling settings. The following PowerShell example is the same local API request structure tested separately on our isolated server:
$request = @{
    model = 'deepseek-r1:8b-0528-qwen3-q4_K_M'
    prompt = 'Reply with exactly: Local DeepSeek ready.'
    think = $true
    stream = $false
    keep_alive = '5m'
    options = @{
        num_ctx = 4096
        num_predict = 2048
        num_thread = 8
        temperature = 0.6
        top_p = 0.95
        seed = 42
    }
} | ConvertTo-Json -Depth 5
$answer = Invoke-RestMethod -Uri 'http://127.0.0.1:11434/api/generate' -Method Post -ContentType 'application/json' -Body $request -TimeoutSec 600
$answer | ConvertTo-Json -Depth 8
In the separate walkthrough check, the command returned final response Local DeepSeek ready. and done_reason=stop. Our test server used isolated port 11435; the reader command above uses the standard 11434. This fourth request is not included in the three-task table.
The response field is the user-facing final answer; thinking is separate for this reasoning model. Check that the request completed and that the final answer meets your instruction. num_ctx=4096 sets the context window for the request; num_predict=2048 limits generated tokens, including thinking. A reply can use that allowance before it produces a usable final answer. The limit is a test setting, not a recommended value for every workload.
After an answer, .\ollama.exe ps reports which model is loaded and its PROCESSOR placement. “100% CPU” in that column means the model resides entirely in system memory; it is not a measure of CPU utilisation. An installed GPU alone does not establish GPU inference.
Unload the model and stop only a server you started
With the normal Windows installer, use ollama stop deepseek-r1:8b-0528-qwen3-q4_K_M and then ollama ps to check that this model is unloaded. This does not remove its downloaded files or shut down the background app.
For the standalone ZIP route, use PowerShell window 2, still pointing to the server you started in window 1. If you are in an interactive chat, type /bye first to return to PowerShell. From the extracted folder, unload the model and check the loaded-model list:
.\ollama.exe stop deepseek-r1:8b-0528-qwen3-q4_K_M
.\ollama.exe ps
Check that this model no longer appears in the ps output. Unloading releases it from memory and keeps the downloaded files in your selected models directory, so you can use them again.
When you have finished using the standalone server, press Ctrl+C in window 1, where you ran .\ollama.exe serve. This stops that foreground server. An installed background Ollama application is a separate process; closing another window does not necessarily stop it. Do not remove other models or a general Ollama directory to free space.
In our separate, unscored walkthrough check after the three tasks, we confirmed a non-empty final response, then used Ollama’s stop and ps commands to verify that the model was unloaded. This check is separate from the three scored requests below.
Troubleshoot the specific Windows route
| What you see | What to check |
|---|---|
ollama is not recognized | For the installer route, reopen PowerShell after installation and check the app. For the standalone ZIP route, open the extracted folder and use .\ollama.exe; the ZIP need not be on PATH. |
| Address in use or connection refused | With the installer, confirm its background app is running and avoid starting a second server. With the standalone ZIP, check the server window and the host/port set in window 2. Identify the instance you intend to use; do not kill an unrelated process. |
| Pull interrupted | Check network and disk space, then retry the exact tag with the same model directory. Our command environment had a blocked first setup attempt and later lost connections; those happened before inference and are not DeepSeek-answer failures. |
| Blank or cut-off final answer | For a local API request, check done, done_reason and the final response. A thinking trace alone does not mean the task is complete. If you retry with a higher output limit, allow more time and check the new final answer against your question. Keep the earlier response if you want to compare the attempts. |
| Unexpected CPU/GPU placement | Use ollama ps after loading the model, or .\ollama.exe ps in the ZIP route. Consult Ollama’s GPU guidance for your hardware; our CPU observation does not predict another machine. |
What happened in our three first requests
These are the unedited first final answers from the exact package and settings below. All three requests completed normally under the output cap. One met its complete fixed check; two did not. This is a small demonstration of specific tasks, not a model-wide success rate.
| Item | Recorded setup |
|---|---|
| Test computer | Intel Core i7-14700; 28 logical processors; Windows 11 build 26200/25H2; 104 GiB installed RAM |
| Runtime and checkpoint | Ollama 0.34.2; deepseek-r1:8b-0528-qwen3-q4_K_M; Q4_K_M; manifest 6995872bfe4c |
| Local model files after pull | 5,225,381,416 bytes in the isolated model directory, including the 5,225,373,760-byte verified weight layer; these are disk sizes, not running RAM |
| Observed placement | Ollama reported 100% CPU placement and a 4,096-token context for all three requests; no GPU inference was observed |
| Request context and output | 4,096 context tokens; up to 2,048 generated tokens, including thinking |
| Thinking and sampling | Thinking enabled; temperature 0.6; top-p 0.95; seed 42; eight configured CPU threads |
| Request design | Three different, fresh, stateless prompts; one first response per task; no regeneration or warm-up generation |
For this isolated CPU baseline, we disabled Ollama’s Vulkan path. The reader setup above does not force this switch, so another computer may use a GPU. We verified the actual placement with ollama ps rather than inferring it from the hardware.
| Task | First outcome | Stop reason | Fixed-check verdict |
|---|---|---|---|
| Order JSON extraction | Seven facts correct, but wrapped in a Markdown code fence | stop | Failed the exact-format check |
| Workshop summary | Three bullets and 29 words; “for adults” became “for adults only” | stop | Failed our strict editorial no-added-facts check |
| Discounted total | Correct final amount of GBP 90.90 with compact calculation | stop | Met the fixed check |
Each example used fictional text and one fresh, stateless request. The prompts and success checks were frozen before inference. We submitted exactly three scored first requests in the order shown; a fourth, unscored PowerShell walkthrough request was run afterward and is disclosed above. The first request began with the model unloaded, while later requests could use a resident model. Because the prompts differ and the operating-system file cache was not cleared, these times are not a cold-versus-warm speed comparison.
Order JSON extraction
Fixed check: One strict JSON object with exact keys, types and values, no code fences or surrounding prose. Key order irrelevant.
Exact prompt:
Return only one JSON object with exactly these keys: order_id, customer, item, quantity, unit_price, currency, delivery_date. Use JSON numbers for quantity and unit_price. Use null for an absent delivery date. Source: Order CED-217 was placed by Mira Hassan for 6 notebooks at GBP 2.75 each. No delivery date is stated.First unedited final response:
```json
{
  "order_id": "CED-217",
  "customer": "Mira Hassan",
  "item": "notebooks",
  "quantity": 6,
  "unit_price": 2.75,
  "currency": "GBP",
  "delivery_date": null
}
```
Failed the exact-format check. The requested keys, values and value types are present inside the fence, but the whole first response is not a raw JSON object. A strict JSON parser rejects it. We did not remove the fence or regenerate the answer.
Workshop summary
Fixed check: Exactly three bullets and no more than 70 whitespace-separated words; Saturday, Cedar Hall, 10:00–11:30, adults, free, refillable bottle, side entrance and repair reason all present; no invented facts. Semantic review required.
Exact prompt:
Summarize the source in exactly three bullets and at most 70 words. Preserve every stated practical detail; add nothing. Source: The Saturday workshop is at Cedar Hall, from 10:00 to 11:30. It is for adults and entry is free. Bring a refillable water bottle. Use the side entrance because the front steps are under repair.First unedited final response:
*   Saturday workshop at Cedar Hall, 10:00 AM to 11:30 AM.
*   For adults only, free entry.
*   Bring refillable water bottle; access via side entrance due to front steps under repair.
Failed our strict editorial no-added-facts check. The answer retained the practical time, venue, price, water-bottle and side-entrance details. It changed the source’s “for adults” to “for adults only.” We treated “only” as a stronger exclusion than the source explicitly stated. That is an editorial precision judgment: a reader may reasonably interpret “for adults” as the same restriction. We preserve our original score, but this example is less clear-cut than the JSON-format failure and should not be presented as an objective factual-error rate.
Discounted total
Fixed check: Final GBP 90.90, confirmed subtotal 96.00, discount 9.60, discounted subtotal 86.40, cancelled posters excluded, delivery added after discount, no more than two sentences.
Exact prompt:
Calculate the final amount in GBP. Confirmed items: 8 badges at GBP 7.50 each and 3 folders at GBP 12.00 each. Cancelled items: 2 posters at GBP 15.00 each; exclude them. Apply a 10% discount to the confirmed-item subtotal, then add GBP 4.50 delivery. Give the final amount and one compact calculation, in no more than two sentences.First unedited final response:
The final amount is GBP 90.90.

Compact calculation: (8 × £7.50 + 3 × £12.00) × 0.90 + £4.50 = £90.90
Met the fixed check. Eight badges at GBP 7.50 and three folders at GBP 12 total GBP 96. Applying the 10% discount gives GBP 86.40; adding GBP 4.50 delivery gives GBP 90.90. The cancelled posters were excluded. The response stays within the two-sentence limit.
Timing and sampled memory
The total wait is measured by our local client. “First final text” begins when the first non-empty final response chunk arrives; it excludes earlier thinking chunks. The generation rate divides Ollama’s reported generated-token count by its reported evaluation duration; it includes thinking tokens and excludes loading and other parts of the wait. These are observations, not a benchmark across machines.
| Task | Total wait | First final text | Generated tokens | Reported generation rate |
|---|---|---|---|---|
| Order JSON extraction | 126.0 s | 105.1 s | 417 | 3.5 generated tokens/s |
| Workshop summary | 80.5 s | 68.1 s | 272 | 3.5 generated tokens/s |
| Discounted total | 224.3 s | 206.9 s | 751 | 3.4 generated tokens/s |
The largest sampled sum of the owned Ollama server and child-process working sets was 5.67 GiB. Samples were taken at nominal 250 ms intervals; they can miss a peak and may count shared pages more than once. This is not a minimum-RAM requirement. The desktop was in active use. The listed 5.2 GB package size, system RAM and this sampled process figure measure different things.
These results describe one package, one active Windows desktop and three small tasks. They do not establish a reliability rate, minimum RAM requirement, full-R1 performance, long-context recall, vision/PDF ability, coding-agent compatibility, GPU speed or a matched comparison with the separate Qwen local guide. We did not disconnect the computer from the internet to audit network isolation. Running a local model avoids a hosted per-token inference bill for these calls, but uses your hardware, disk and electricity.
Read the complete test records as plain text (TXT, 362 KB) or download the original records and criteria (ZIP, 42 KB). They include the frozen prompts, all three raw streams with thinking and final fields, exact manifest, runtime settings, measurements, mechanical checks, editorial assessment and the separately labelled PowerShell demonstration. No model binary, local profile, API key or private server log is included. The unedited first final answers also appear above as text.
DeepSeek Chat, its hosted developer API and this downloaded package are different products and routes. Use the DeepSeek overview for the official assistant, the model guide for release selection and licenses, and the API guide for hosted calls. ChinaAI is independent of DeepSeek and Ollama. Report a correction with the affected command, exact tag/version and a reproducible example. We review this guide when the tag/manifest, runtime packaging or observed workflow changes.